If you’re a developer or DBA working with SQL Server, you’ve probably had this conversation before:
“Hey, can I get a copy of production for testing?”
“Sure, just scrub the sensitive data first.”
“Scrub it how?”
And that’s where things get complicated. You could write update scripts. You could build ETL pipelines. Or you could let SQL Server handle it for you with Dynamic Data Masking.
Let’s cut through the marketing noise and look at how this actually works in practice.
What SQL Server Actually Gives You
Dynamic Data Masking has been around since SQL Server 2016. It’s not a third-party tool. It’s not something you buy separately. It’s built right into the engine.
The concept is refreshingly simple. You define masking rules on specific columns. When a user without UNMASK permission queries the table, they see masked data. Users with the right permissions see the real values. No data duplication. No ETL jobs. No scheduled refreshes.
Here’s what that looks like in code:
The partial(1,”-“,1) function on FullName shows the first character, then a dash, then the last character. “Sarah Johnson” becomes “S-n”. The email function turns “sarah@company.com” into “s*@c**.com”. The default function on Phone returns “xxxx” for every character. CreditCard shows only the last four digits.
The Permission Model Is Everything
Dynamic Data Masking works entirely through permissions. It’s not encryption. It’s not row-level security. It’s column-level obfuscation that happens at query time.
You control access through the UNMASK permission:
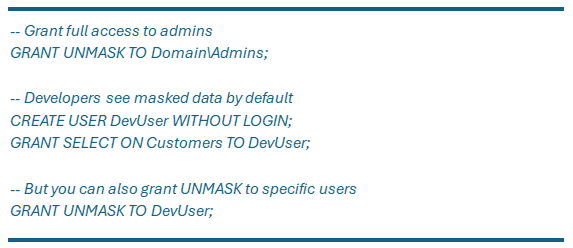
The interesting part is that UNMASK works alongside your existing SELECT permissions. If a user can’t SELECT from a table, masking doesn’t matter. If they can SELECT but don’t have UNMASK, they get masked values.
This is where most people get it wrong. They grant UNMASK to everyone and then wonder why masking isn’t working. The default permission is masked. UNMASK is the exception. Design your security that way.
Testing the Masking Logic
Before you apply masking to production, test it thoroughly. SQL Server Management Studio makes this easy:
You’ll see the masked values immediately. No guesswork. If something looks wrong, adjust the masking function and test again.
The Performance Myth
I’ve heard people argue that dynamic masking adds too much overhead. In practice, it’s negligible for most workloads.
SQL Server applies masking during the query execution phase. It doesn’t affect the query plan. Your indexes work normally. Your joins perform as expected. The masking logic runs on the result set, not during data retrieval.
However, there’s a performance hit if you’re returning millions of rows. Every masked column triggers a function call for each row. If you have ten masked columns and you’re pulling 5 million rows, that adds up.
The solution is simple: don’t mask columns you don’t need. Test queries with actual masked data. If you see a performance problem, consider applying masking to a view instead of the base table.
The Implementation Trap
Here’s the most common mistake I see:
This works. But you’re now stuck with that masking rule unless you explicitly remove it.
Better approach: define your masking requirements during table creation or in a separate migration script. Keep all masking definitions in source control. If you need to change a rule, you have a clear audit trail.
What Dynamic Masking Doesn’t Do
Let me be clear about the limitations.
First, it doesn’t encrypt data. The underlying values are still stored in plain text. If someone gets direct filesystem access to your database files, they can read everything.
Second, it doesn’t protect against schema exports. When you export a database backup, the masked columns are still in plain text. You need backup encryption or separate handling for test environments.
Third, it doesn’t help with developers who need to run queries on production. If someone with UNMASK runs a query, they see real data. You can’t selectively mask based on time of day or IP address. It’s all or nothing at the permission level.
Building a Hybrid Approach
For true safety, combine dynamic masking with other techniques:
This gives you more control than the built-in functions. You can use business rules, session variables, or any logic you can express in T-SQL.
When to Use Dynamic Data Masking
Dynamic Data Masking is useful when users need access to production data but shouldn’t see sensitive details.
Good for:
- Support teams troubleshooting production issues
- Reports that don’t require full data
- Third-party vendors with limited access
- Auditors who need structure, not personal details
Not for:
- Full database protection → Use encryption
- Developer test data → Use static masking
- Row-level access control → Use RLS
The Bottom Line
Dynamic Data Masking is simple and useful, but it isn’t a complete security solution. It helps prevent accidental exposure of sensitive data while allowing necessary database access.
Sometimes, simple security controls are the most effective.
Author By

